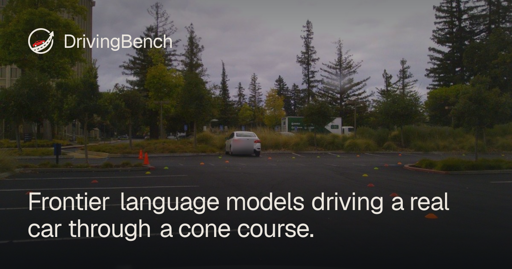
A benchmark where frontier language models drive a real comma-equipped Toyota through a cone course, one command at a time, with a human supervisor ready to brake.
Why the hell would you give a language model the wheel of a car?
They don’t even understand the concept of time and space. Some of them can parse an image, but typically only enough to pull text from it, and extremely slowly.
It’s like asking an overweight English teacher to play pro football.
We built visual recognition machine learning systems for this purpose.

Why the hell would you give a language model the wheel of a car?
They don’t even understand the concept of time and space. Some of them can parse an image, but typically only enough to pull text from it, and extremely slowly.
It’s like asking an overweight English teacher to play pro football.
We built visual recognition machine learning systems for this purpose.
They’re better drivers than low IQ humans